Data Connections
Platform (dbtCharts.com)
This page describes dbt Charts Platform, the
hosted product at dbtCharts.com. These features are not part of the
open source dct engine.
Boards never embed credentials; YAML names a source (source:
warehouse) and Platform resolves the name to a connection: warehouse
credentials stored once at the organization level and shared across the
org's projects. Only org admins manage connections.
Supported warehouses
dbt Charts only reads, so the credential you provide should be a read-only one, not the credential your dbt project builds with. See warehouse privileges for how to create one and grant it access.
| Type | You provide |
|---|---|
| PostgreSQL | Host, database, username, password. Optional: port (5432 when blank), schema (public when blank). SSL is required by default. |
| Redshift | Host, database, username, password. Optional: port (5439 when blank), schema (public when blank). |
| Snowflake | Account, warehouse, database, username, and one credential: a key-pair (recommended), a programmatic access token, or a password (deprecated; Snowflake is retiring password sign-in). Optional: schema (PUBLIC when blank). Snowflake only accepts an access token from a user with a network policy, which must allow Platform's egress IPs. |
| BigQuery | The service-account JSON key file: drop it on the form and the project fills itself in. List datasets shows the datasets that key can read, then pick one. The dataset's location is read from BigQuery, never typed. |
| Databricks | Host, the SQL warehouse's HTTP path, catalog, and either a service principal (client ID and client secret, recommended) or a personal access token. Optional: schema. The principal needs CAN USE on the SQL warehouse; use a service principal when your admins have turned tokens off. The catalog is the Unity Catalog catalog your tables live in: List catalogs shows the ones the credentials can see, or browse Catalog Explorer in your workspace. The credential needs USE CATALOG on the catalog; the connection test checks it. |
| Trino | Coordinator host, catalog, schema, and username. Optional: port (443 with SSL, 8080 without) and a password (LDAP) or a JWT. Works with Starburst too. A password or token is only sent over HTTPS, so Require SSL must stay on when one is set. |
Network access
Platform queries your warehouse over the public internet, from one fixed address. The warehouse has to be reachable from there: a host on a private or internal network address is rejected when you save, and a warehouse reachable only through a VPN, a private endpoint, or an SSH tunnel cannot be reached at all.
If your warehouse restricts inbound traffic by address, allow:
Every query dbt Charts runs leaves from that address, so one rule covers every connection in your organization. Clones and pushes to a self-hosted Git server leave from it too.
Where the rule goes depends on the warehouse:
| Warehouse | Where to add it |
|---|---|
| PostgreSQL | Your provider's allowlist (Cloud SQL authorized networks, an RDS inbound security-group rule, an Azure firewall rule), and a pg_hba.conf entry as well if the server restricts by client address. |
| Redshift | The cluster's security group, inbound on the port you connect to. The cluster also has to be publicly accessible. |
| Snowflake | A network policy: add the address to its ALLOWED_IP_LIST. |
| BigQuery | Nothing. BigQuery grants access through IAM rather than by address, so there is no inbound allowlist to edit. The one exception is a VPC Service Controls perimeter around the dataset, where the address belongs in an access level. |
| Databricks | The workspace's IP access list, not a cluster security group. This applies to serverless SQL warehouses too, since the connection targets the workspace URL rather than the warehouse's own compute. |
| Trino | Whatever fronts the coordinator: its load balancer's or security group's inbound rules for the coordinator port. |
Allowing the address lets our traffic reach your warehouse; it does not authenticate it. The credential does that, so keep it scoped; see warehouse privileges.
Testing and saving
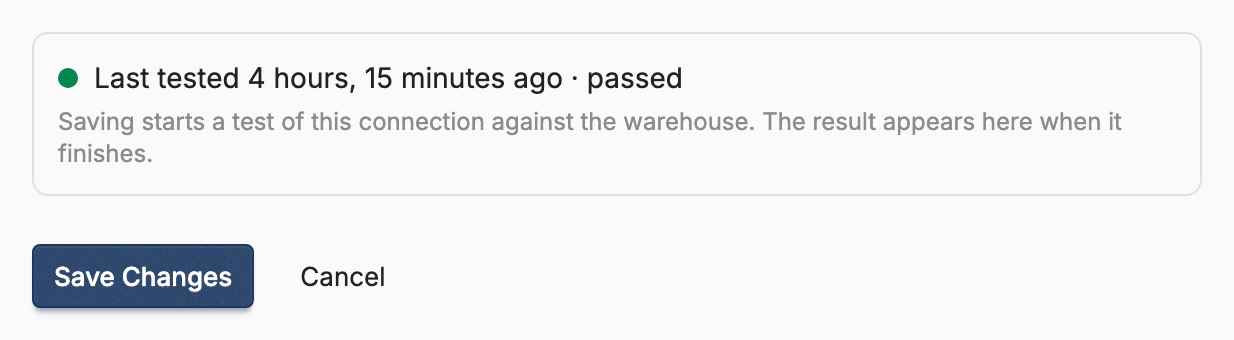
There is no separate test step. Save is the only action on the form, and saving starts a test of the credentials against the warehouse in the background. The page returns at once with the connection saved; the status block beneath the form reads "Testing…" and updates in place when the result lands, with no reload. The block always shows the connection's most recent test: "Not tested yet" before the first one, "Testing…" while one runs, and otherwise when it finished and whether it passed. A failure also shows the warehouse's own error beneath the form.
One case is neither pass nor fail. If the check cannot finish in time, the warehouse may still be starting up, so nothing was proved either way: the connection saves without recording a failure that never happened, and the block says the test did not finish. Re-check it once the warehouse is up.
The form keeps a failed connection because editing it here is one field and one
click. dct cloud connection create
has no edit verb, so it does the opposite: a test that fails outright saves
nothing, and the retry is the same command once you have fixed whatever the
printed error names. A test
that could not finish in time is the exception. The warehouse may still be
starting up, so nothing was disproved and the connection is kept. Re-run the
check with dct cloud connection test <slug> rather than the create command,
which would collide with the slug already taken.
To re-run the checks on a saved connection, save it again (leaving a secret field blank keeps the stored value), or use Re-check readability on the connection's page. Both re-test the credentials and re-run the readability check.
Readability
A credential can sign in and still be missing access to one table, and that gap would otherwise surface later as a broken board. The Readability card on a connection's page checks for it up front: can this credential read every table the boards in each project query?
The check runs in the background after every save, and again when you choose Re-check readability. Re-checking keeps any unsaved edits in the form but checks the saved settings, so save first to check new ones. The card shows the previous result until the new one lands; reload the page to see it.
It first confirms the credential can connect. Then, for each project the
connection is mapped into, it finds every table that project's boards read
through this connection and sends the warehouse SELECT * ... LIMIT 0 against
each one. No rows are read or returned. The warehouse only confirms it accepts
the statement, so a grant that exists on paper but does not work still shows up.
Results are listed per project, because one connection can serve several.
| Status | Meaning |
|---|---|
| All relations readable | Every table checked was readable. |
| Unreadable relations found | At least one table failed. Each one is listed with the warehouse's error. Grant the role access, then re-check. |
| Some checks could not be completed | A board would not compile, a query's tables could not be determined, a check timed out, or the project's dbt_charts.yml would not load. The card names each one. A timeout does not mean the table is unreadable. |
| Nothing to verify | No board in the project queries this connection. |
| Could not connect | The credential failed its connection test. The error is shown, and no tables were checked. |
Only boards on the project's main branch are checked, and only queries that resolve to this connection. When a table is unreadable, the Generated grants config card below it lists the grants to apply, narrowed to the tables your boards read.
Generated grants config
On PostgreSQL, Redshift, Snowflake, and BigQuery connections, the Generated
grants config card sits below Readability. It turns the readability results
into the statements that give the read-only role access to exactly the tables
your boards read, instead of to a whole schema. The role is the one from
Warehouse privileges: dbt_charts_ro, or the
dbt-charts-ro service account on BigQuery. Other connection types show no
card.
For each project, the card shows up to two blocks, each with a copy button:
- dbt grants config: a
config.grants.selectblock for the tables dbt builds. Add it to the model's existing properties entry, or create one if it has none. It takes effect on your nextdbt run. - Raw-source SELECT DDL: a
GRANT SELECTstatement for each table dbt does not build.
A table counts as built by dbt when its name matches a .sql file in the
project's model paths. When the card cannot tell, for example because it finds
no dbt_project.yml or two tables share a model name, it lists the table in
both blocks and says so. Tables whose queries could not be analyzed are left
out and named beneath the blocks.
Platform only generates this text. It never runs the statements and never changes
your project, so you apply them yourself and then choose Re-check
readability to confirm. Until a readability check has run for a project, the
card asks you to run one. Grant dbt-built tables through the grants block
rather than by hand; see
why hand-written grants and dbt do not mix.
Who can query a connection
A new connection is queryable by every member whose organization role allows querying. This is the organization default, and it starts as Editor. Viewers never query a connection directly.
An admin can change the default's role or set it to No access. With No access, only organization admins and principals with their own grant can query the connection.
Grants to individual people or teams work independently of the default. Manage them in the Permissions card on the connection's page, or see every connection's grants in one place under Settings → Access → Who has access, in its Connections section. Filter that table by person, team, identity group, or role to answer "who can query the warehouse?" or to review what someone can reach before they leave. The same table, filtered to one person, is the Connections section of their page under Settings → Members.
Organization admins can manage every connection whatever the grants say. A grant to an organization Viewer reads "No access" with an "Org Viewer · cannot query connections" badge, because Viewers cannot query connections. A grant to someone who has since left the organization is marked "Not a member": it still applies, and you can remove it but not change its role.
Mapping sources
Platform reads the source names your project's dbt_charts.yml declares on your
project's working branch, the branch Platform edits and renders from. That file
is the declaration, and it is the only place Platform looks. A name a board
writes as source: warehouse is a reference to a declaration, not one itself:
if dbt_charts.yml never declares it, it appears nowhere on this page and
every chart that uses it fails to compile, with the error pointing back here.
Each declared name that names a warehouse starts with no connection;
boards and chat can't query it until someone who manages a connection of the
same warehouse type connects one. csv, json and parquet sources never
need one: they read files already in your repo.
You can connect a source from either side:
- From the project. Settings → Data Sources lists every source with its connection, who can query that connection, and its schema. A source with no connection has an + Add connection menu listing the organization's connections of the same warehouse type. + Add source declares a new source and connects it in one step. Connections the project doesn't use yet are listed under the table, each with Add as a source.
- From the connection. A connection's page has a Sources section listing every project source that uses it. + Add to a project connects it to a source a project already declares, or starts a new source in a project. When you create a connection, Use in projects does the same before you save, and saving takes you to the connection's page.
A source and its connection must be the same warehouse type: a source declared
type: snowflake only takes a Snowflake connection. A connection reaches
boards and chat only through a source, so a new connection that no source uses
can't be queried yet.
Each source can set a schema: where a query that names a bare table, like
select * from orders, looks. It defaults to the connection's own schema. Pick
another from the connection's schemas when one project reads a different
schema than the connection's default. BigQuery and DuckDB connections don't
take one.
The star at the end of a row marks the project's default source. Mapping one existing source or adding a source when the project has no default makes it the default automatically. If you map several existing sources together, select the intended default's star. Adding another source keeps the existing default; select another source's star to change it.
Declarations live in git and mappings live in Platform, so the two move on different clocks: a source appears here as soon as it lands on the working branch, and the connection you pick for it belongs to the project, not to the branch: it stays picked once that branch merges.
A warehouse source's credential fields in dbt_charts.yml (password:,
keyfile:, or an env_var() standing in for one) are for rendering locally.
Platform ignores them; the connection you map here is what a render uses. A dbt
profile that already works locally does not connect Platform to your warehouse:
create a Platform connection and map it to the project's source. Use the database
and base schema or dataset from your production dbt target. dbt Charts applies
model and package schema settings when resolving refs. Keep ref() and
source() in your boards so the same SQL works across projects.
The project's default source is also the one ref() and source() resolve
against: Platform lists its tables to link each dbt model to its production relation
(how it resolves). Its credentials must be
able to list tables in the schemas your production dbt run builds into; a source
that cannot is recorded as a failed index build and ref() charts keep failing
until it can.
Mapping, re-mapping or unmapping a source re-renders the project's boards: a
render resolves its sources when it runs, so every render made before the
change is stale. A project's first render happens at sync, before anything is
mapped, and its boards show ERR-SOURCE-NOT-FOUND until the mapping lands
and that re-render completes. To re-render on demand, a project admin
runs dct cloud render --force.
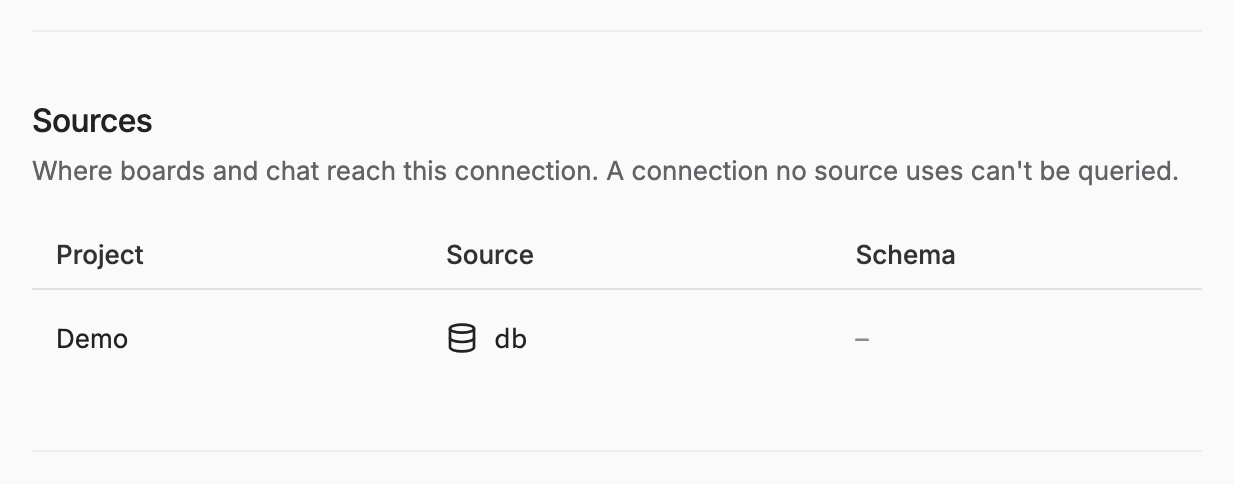
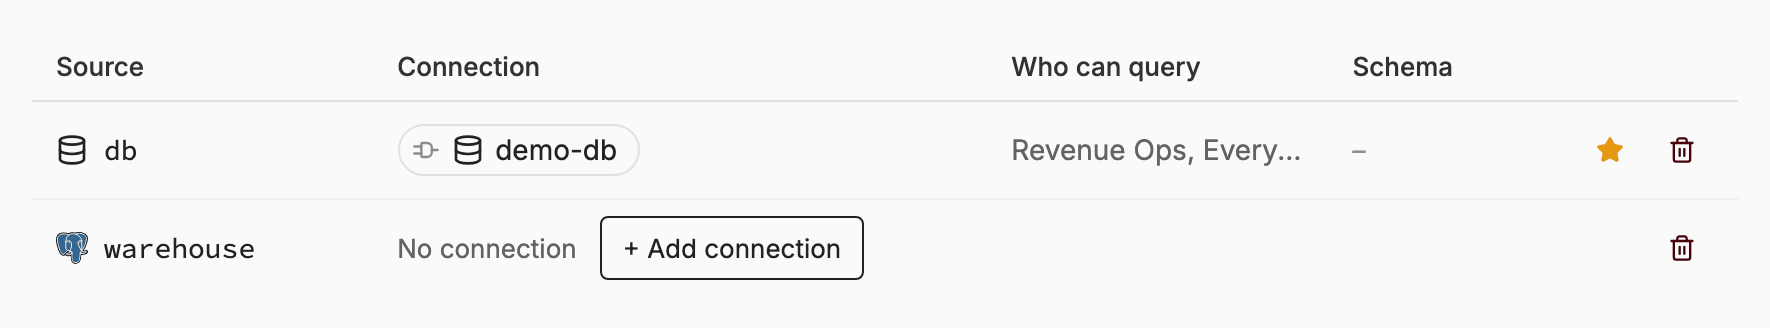
Because connections are org-level and mappings are per-project, two projects can point the same source name at different warehouses, or share one connection.
Pre-filling from dbt profiles
If the repo has a committed dbt profiles.yml, Platform uses it to pre-fill
the non-secret fields of a new connection: host, database, project,
dataset, and so on. Credentials are never read from the repository; secrets
are always entered directly in Platform.
How credentials are handled
- Credentials are encrypted at rest.
- Secrets are write-only: passwords and keys are never displayed back, and leaving a secret field blank when editing keeps the stored value.
- Connection management requires the org Admin role; which boards a member can query is governed separately by access control.
- How much the credential can reach is up to you: warehouse privileges covers granting it read access to the tables your boards need, and nothing else.
Related
- Warehouse privileges: creating a read-only role and granting it access
- Getting started: the full setup flow
- Sources: how the open source engine defines and uses sources in YAML